
How Many Tokens Is a Word? Measured Across 14 LLMs
A 1,000-word English text came to 1,151 tokens on GPT-4o and about 1,737 on Claude Opus 5.5. Tokens per word for 14 models, three languages and code.
 Photo by InTellIGentFan on Pixabay
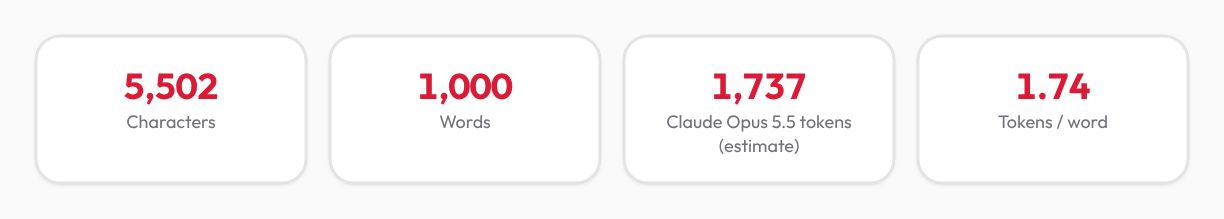
In English, one word is about 1.15 tokens on GPT-4o. We wrote a 1,000-word text and counted it: 1,151 tokens. On Claude Opus 5.5 the same text comes to about 1,737 tokens, so closer to 1.7 tokens per word, and that number is an estimate (more on why below).
The rules of thumb you have probably seen are close, but not that close. OpenAI’s help article on what tokens are (checked 2026-10) says “100 tokens ~= 75 words”, which puts 1,000 words at about 1,333 tokens. Our text came in about 14% under that on GPT-4o and about 30% over it on Claude Opus 5.5. Which model reads the text matters more than the rule.
How many tokens is 1,000 words?
The test text is three ordinary pieces of English, written for this article and joined into exactly 1,000 words: a how-to on setting up a guest Wi-Fi network, a short scene in a Lisbon bakery, and an online shop’s returns policy. Instructions, narrative and formal prose, the kind of thing people paste into a chatbot every day. We counted it with one model from each tokenizer family the Token Counter supports, plus GPT-4’s older cl100k_base.
Tokens per 1,000 English words, by model
| Tokens for 1,000 words | Words in 1,000 tokens | |
|---|---|---|
| GPT-4o (o200k_base) | 1,151 | 869 |
| GPT-4 (cl100k_base) | 1,159 | 863 |
| GPT-6.1 Sol (est.) | 1,167 | 857 |
| Claude Opus 5.5 (est.) | 1,737 | 576 |
| Claude Haiku 4.5 (est.) | 1,353 | 739 |
| Gemini 3.1 Pro (est.) | 1,282 | 780 |
| Grok 4.7 (est.) | 1,206 | 829 |
| DeepSeek V4 Pro | 1,165 | 858 |
| Qwen3.8 Max | 1,178 | 849 |
| Mistral Small 4 | 1,180 | 847 |
| Gemma 4 31B | 1,173 | 853 |
| Kimi K3 | 1,155 | 866 |
| GLM-5.3 | 1,160 | 862 |
| Muse Glimmer 30B | 1,161 | 861 |
Counted 2026-10-28 on one 1,000-word English text. Rows marked (est.) are the Token Counter’s calibrated estimates and include the few tokens each provider adds to wrap text as a message; every other row is exact.
Calculated with the same logic as our Token Counter & Cost Calculator: GPT, Claude, Gemini, DeepSeek and more.
Ten of the fourteen rows sit between 1,151 and 1,180 tokens, including all nine exact counts: two OpenAI encodings and seven open-weight models from DeepSeek, Alibaba (Qwen), Mistral, Google (Gemma), Moonshot (Kimi), Zhipu (GLM) and Meta. The GPT-6.1 Sol estimate lands in the same band. On this text, modern tokenizers have converged. If your model is one of them, 1.15 to 1.18 tokens per word is a measured answer, not a guess.
The other estimates spread out. Grok 4.7 lands at 1,206 and Gemini 3.1 Pro at 1,282, which fits Google’s own token guide (checked 2026-10): “100 tokens is equal to about 60-80 English words”, so 1,250 to 1,667 tokens for 1,000 words. Then there is Claude.
Why Claude needs more tokens per word
Anthropic changed tokenizers. Its token counting docs (checked 2026-10) say Claude 4.7 and later models use a newer tokenizer and that “the same input text produces approximately 30 percent more tokens than on earlier models.” Our calibrated estimates, fitted to Anthropic’s exact counts, agree: Claude Haiku 4.5, still on the older tokenizer, comes to 1,353 tokens for the 1,000 words, and Claude Opus 5.5 to 1,737. That is 28% more, close to Anthropic’s figure.
Anthropic doesn’t publish a tokenizer you can run, so both Claude numbers are estimates. The Token Counter starts from an open OpenAI encoding and corrects it with factors fitted against Anthropic’s own exact counts over 16 texts. On that set the Opus 5.5 estimate was off by 8.1% on average and 19.8% at worst. Good enough for a budget, not for an invoice: counting Claude tokens covers how to get the exact number from Anthropic when you need it.
In practice, a prompt that fits comfortably on GPT-4o needs roughly half again as many tokens on Claude Opus 5.5. 1,000 tokens hold about 869 words on GPT-4o and about 576 on Opus 5.5. If you compare prices per million tokens across providers without converting to words first, Claude looks cheaper than it is.
Tokens per word in other languages and in code
Every ratio above is for English. To see how far it moves, we translated the Wi-Fi how-to (408 words) into Persian and Chinese, keeping every step, and also counted two short programs: a TypeScript function that summarises a day’s orders and a Python script that totals a CSV by month. Chinese doesn’t put spaces between words, so a “word count” for it means little. To keep the languages comparable, both translations are divided by the 408 words of the English original: the question becomes how many tokens it takes to say what 100 English words say.
Tokens per 100 words: the same guide in three languages, and code
| English | Persian | Chinese | Code | |
|---|---|---|---|---|
| Words | 408 | 408 | 408 | 227 |
| GPT-4o (o200k_base) | 114 | 175 | 128 | 222 |
| GPT-4 (cl100k_base) | 114 | 389 | 181 | 225 |
| DeepSeek V4 | 115 | 209 | 107 | 236 |
| Claude Opus 5.5 (est.) | 173 | 342 | 163 | 317 |
| Gemini 3.1 Pro (est.) | 127 | 191 | 113 | 231 |
Counted 2026-10-28. Persian and Chinese are per 100 words of the English original (408 words), so all three language columns measure the same content. Code is per 100 whitespace-separated “words” of its own, as the Token Counter counts them.
Calculated with the same logic as our Token Counter & Cost Calculator: GPT, Claude, Gemini, DeepSeek and more.
English is the steady column: 114 tokens per 100 words on both OpenAI encodings, 115 on DeepSeek. Persian is where the tokenizer really matters. GPT-4’s cl100k_base needs 389 tokens to say what 100 English words say, 3.4 times the English count; GPT-4o’s newer encoding cuts that to 175. Chinese is cheapest on DeepSeek, at 107, which is slightly below its own English figure.
Code costs the most per word. At 222 tokens per 100 words on GPT-4o, it costs nearly twice as much per word as prose, because a “word” in code is often something like order.items.reduce((sum, with brackets, dots and operators that each take a token. Budget code by characters or by measuring it, never by word count. If you want to see where the extra tokens go, one text, five tokenizers shows the per-character counts and how the pieces split.
Corpus: a 1,000-word English text (a Wi-Fi how-to, a short story scene and a returns policy), the how-to’s Persian and Chinese translations, a TypeScript function and a Python script, all written for ZipTools and committed to the site’s repository so anyone can rerun them. Words are whitespace-separated, as the Token Counter counts them. OpenAI encodings were counted with the gpt-tokenizer library the Token Counter uses, and open-weight models with each model’s published tokenizer file, the same one the Token Counter loads; all of those count the raw text with no chat template. GPT-6, Claude, Gemini and Grok rows are the Token Counter’s estimates, calibrated on 2026-10-12 against each provider’s exact counts over 16 texts. Counted 2026-10-28; the site’s test suite reruns every number on each change.
Check tokens per word on your own text
Your writing won’t match ours exactly. Long technical words, lots of numbers or names, and Markdown formatting tend to push the ratio up. The Token Counter shows words, tokens and tokens per word side by side for whichever model you pick, so you can check your own drafts instead of trusting a rule. Here is the tool with our 1,000-word text and Claude Opus 5.5 selected:
It runs in your browser, so nothing you paste is uploaded unless you switch on a provider’s exact count. Once you know the token count, the LLM Cost Calculator turns it into a monthly bill for a given number of requests.
When a words-to-tokens rule is good enough
For a rough sense of size in English, 1.15 to 1.2 tokens per word works on most models. The familiar 75-words-per-100-tokens rule, explained in how AI reads your text, overestimates a little on every model in our table except Claude: it is about right for Haiku 4.5, and Opus 5.5 needs about 30% more than it predicts. Overestimating is the safe direction for a budget; underestimating is how a prompt stops fitting.
Measure instead whenever money or a hard limit is involved: Claude 4.7 and later, any language other than English, code, or a prompt that has to fit a context window with little room to spare. Our test text is one sample of everyday prose. Yours is the one that gets billed.
Mahdi Moradi
Full-stack software engineer and founder of Bornara AI, building free privacy-first tools at ZipTools. Based in Calgary, Canada.
Try the tool mentioned in this article.
Open token counterRelated articles

How AI Background Removal Works — The Technology Behind Instant Cutouts
Neural networks can separate foreground from background in seconds. Here's how the technology works, why client-side processing matters, and how to get the best results.

WebP vs AVIF vs PNG vs JPEG: Which Format to Use (Tested)
We ran a real photo and a screenshot through every format and quality level. WebP won both, PNG grew, and AVIF needs more than a browser to make.

How AI Reads Your Text: Tokens, Costs, and Context Windows Explained
Language models do not read words — they read tokens. Understanding tokens is the key to predicting what an AI request will cost and whether your prompt will even fit. Here is how it works, in plain English.