
DeepSeek Token Counter: Exact Counts, Prices and Limits
DeepSeek publishes its tokenizer, so DeepSeek V4 token counts can be exact in your browser. Measured against GPT-4o, plus prices and the 1M token limit.
 Photo by Solen Feyissa on Unsplash
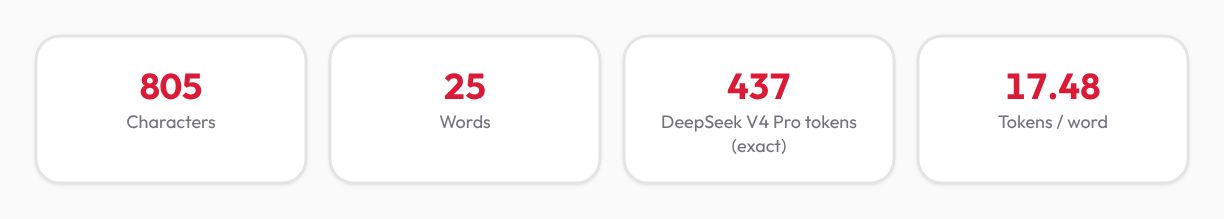
DeepSeek publishes its tokenizer, so a DeepSeek token count doesn’t have to be a guess. A 408-word English how-to comes to 468 tokens on DeepSeek V4, counted with DeepSeek’s own tokenizer file. GPT-4o counts the same text at 465. Translate the how-to into Chinese and the two split: 437 tokens on DeepSeek, 521 on GPT-4o.
So for English the GPT numbers you already know are close enough. For Chinese and Persian they aren’t, and the gap runs in both directions. Below: how to count DeepSeek tokens exactly, where its tokenizer differs from OpenAI’s, what a token costs, and how much fits in the context window.
How to count DeepSeek tokens exactly
Paste your text into the Token Counter and pick DeepSeek V4.1 Flash or DeepSeek V4 Pro. The page loads a copy of DeepSeek’s tokenizer file once per visit (taken from DeepSeek’s MIT-licensed V4.1 Flash release on Hugging Face) and counts in your browser, so the text never leaves your device. Both models get the same V4 tokenizer in the tool. When it has loaded, the tokens box says “exact” instead of “estimate”.
DeepSeek’s own token usage page (checked 2026-11) offers the same thing as a download: a demo tokenizer package you run yourself. It also says the count each API response reports in its usage field is the real one. That matters because our count, like DeepSeek’s offline package, covers the raw text. A real request wraps your messages in a chat format, and thinking mode (the default for both V4 models) adds reasoning to the reply, so the usage figure is what ends up on the invoice.
DeepSeek’s tokenizer vs GPT-4o’s
To see where the two tokenizers part ways, we counted seven texts under both: the Wi-Fi how-to from how many tokens is a word in English, Chinese and Persian, two short programs, a JSON order record and an emoji-heavy social post. GPT-4o stands in for OpenAI because its o200k_base encoding is public and exact too, so both columns are real counts, not estimates.
DeepSeek V4 vs GPT-4o: tokens for the same text
| DeepSeek V4 | GPT-4o | Difference | DeepSeek V4 per character | |
|---|---|---|---|---|
| English how-to (2,247 characters) | 468 | 465 | +1% | 0.21 |
| Chinese how-to (805 characters) | 437 | 521 | −16% | 0.54 |
| Persian how-to (2,233 characters) | 854 | 713 | +20% | 0.38 |
| Python script (659 characters) | 168 | 159 | +6% | 0.25 |
| TypeScript function (1,201 characters) | 367 | 346 | +6% | 0.31 |
| JSON record (598 characters) | 249 | 239 | +4% | 0.42 |
| Emoji post (318 characters) | 123 | 116 | +6% | 0.39 |
Counted 2026-11-02 with each tokenizer on the raw text. Difference is DeepSeek V4 compared with GPT-4o. The last column is DeepSeek tokens divided by characters, the unit DeepSeek’s own rule of thumb uses.
Calculated with the same logic as our Token Counter & Cost Calculator: GPT, Claude, Gemini, DeepSeek and more.
English, code, JSON and emoji all land within 6% of GPT-4o, with DeepSeek a little higher every time. If you budget DeepSeek work in English with a GPT token count, you’ll be off by a few percent. Usually that’s fine.
Chinese is where DeepSeek pulls ahead. Its tokenizer needs 437 tokens for the Chinese how-to against GPT-4o’s 521, 16% fewer. Persian goes the other way: 854 tokens on DeepSeek, 20% more than GPT-4o. Why vocabularies favour some languages, and how Claude and Gemini compare, is covered in one text, five tokenizers.
DeepSeek’s docs give a rule of thumb: “1 English character ≈ 0.3 token” and “1 Chinese character ≈ 0.6 token”. The Chinese half holds up, with 0.54 on our how-to. The English half runs high. We measured 0.21 tokens per character on English prose (counting spaces; DeepSeek doesn’t say whether it does), so the rule runs about 40% high. That’s safe for a budget, but it will tell you a long prompt doesn’t fit when it does.
DeepSeek token price: what a token actually costs
DeepSeek’s Models & Pricing page (checked 2026-11) lists two models. DeepSeek V4.1 Flash costs $0.30 per million input tokens and $1.20 per million output tokens; DeepSeek V4 Pro costs $1.32 and $3.96. Those are peak rates. Peak means 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays, excluding Chinese public holidays; every other hour is off-peak and costs half.
Cheaper per token doesn’t always mean cheaper per text, because each model counts the same text differently. So the table below prices one realistic job, the Chinese how-to sent as input 100,000 times (think of it as a support bot’s Chinese instructions), with each model’s own token count.
Price per token, and the cost of sending one Chinese text 100,000 times
| Input per 1M tokens | Output per 1M tokens | 100,000 × Chinese how-to (input) | |
|---|---|---|---|
| DeepSeek V4.1 Flash | $0.30 | $1.20 | $13.11 |
| DeepSeek V4 Pro | $1.32 | $3.96 | $57.68 |
| GPT-6 Luna (est.) | $0.10 | $0.50 | $4.94 |
| GPT-4o mini | $0.15 | $0.60 | $7.82 |
| Qwen3.8 Flash | $0.15 | $0.47 | $6.33 |
| Gemini 3.5 Flash-Lite (est.) | $0.30 | $2.50 | $13.89 |
| Claude Haiku 4.5 (est.) | $1.00 | $5.00 | $69.30 |
| GPT-6.1 Sol (est.) | $2.00 | $10.00 | $98.80 |
Prices per 1M tokens from the Token Counter’s price list (peak rate for DeepSeek, standard rate elsewhere, as of 2026-10-07; DeepSeek rechecked 2026-11-02). Last column: the Chinese how-to counted per model, times 100,000, input only. Rows marked (est.) use the Token Counter’s calibrated estimate for the token count.
Calculated with the same logic as our LLM API Cost Calculator: monthly cost for GPT, Claude, Gemini and more.
The surprise here: at peak rates DeepSeek V4.1 Flash isn’t the budget winner. Sending the Chinese how-to 100,000 times costs $13.11 on Flash and $7.82 on GPT-4o mini, even though GPT-4o mini needs more tokens for it. Qwen3.8 Flash comes in lower still, and so does GPT-6 Luna, though its count is an estimate. Off-peak, Flash’s input price halves to the same $0.15 as GPT-4o mini, and then its smaller Chinese count puts it slightly ahead of GPT-4o mini, at half of $13.11 (Qwen3.8 Flash and GPT-6 Luna still cost less).
The bigger lever is caching. Input that hits DeepSeek’s cache bills at the cache-hit rate: $0.006 per million on Flash and $0.044 on Pro at peak ($0.003 and $0.022 off-peak). That is 2% of the normal input price on Flash and about 3% on Pro. For input that repeats across requests, like a long system prompt, that is close to free. Output is the side caching can’t touch.
DeepSeek token limit: 1M context, 384K output
Both V4 models take a context of 1M tokens and can write up to 384K tokens of output, per the same pricing page. The context counts everything in a request: system prompt, conversation history, documents and the reply. The Token Counter uses 1,000,000 for DeepSeek and tells you how many tokens of context are left once you set aside room for the answer.
In our tokens-per-word study we measured 1,000 tokens holding 858 English words on DeepSeek V4 Pro, so a full 1M-token context holds roughly 858,000 words of everyday English. Persian and code fill it faster; Chinese, on DeepSeek, slightly slower than the same text in English. The reply has to fit in the same space.
Corpus: the 408-word English how-to from our tokens-per-word study and its Chinese and Persian translations, a Python script, a TypeScript function, a JSON order record and an emoji post, all written for ZipTools and committed to the site’s repository. DeepSeek V4 was counted with the tokenizer file the Token Counter loads (from DeepSeek’s V4.1 Flash release, MIT licence), GPT-4o with the gpt-tokenizer library’s o200k_base, both on the raw text with no chat format, each file trimmed of its final newline (so a count can differ by one from our five-tokenizer article). Prices come from the Token Counter’s price list; DeepSeek’s were rechecked against its pricing page on 2026-11-02. The site’s test suite reruns every number on each change.
From a token count to a monthly bill
Once you have an exact count from the Token Counter, type it into the LLM Cost Calculator with your requests per day and a typical reply length to see the month at peak prices. One caveat: when you paste text into the calculator, it counts DeepSeek with a stand-in tokenizer and marks the result as an estimate. Counting first in the Token Counter and typing the number in is the exact route.
If all your traffic runs in DeepSeek’s off-peak hours, halve the result; if part of it does, take that share off at half price. The rest, thinking-mode output and cache hits, only shows up in the usage figures of real requests, so check a day of those before you commit to a budget.
Mahdi Moradi
Full-stack software engineer and founder of Bornara AI, building free privacy-first tools at ZipTools. Based in Calgary, Canada.
Try the tool mentioned in this article.
Open token counterRelated articles

How AI Background Removal Works — The Technology Behind Instant Cutouts
Neural networks can separate foreground from background in seconds. Here's how the technology works, why client-side processing matters, and how to get the best results.

WebP vs AVIF vs PNG vs JPEG: Which Format to Use (Tested)
We ran a real photo and a screenshot through every format and quality level. WebP won both, PNG grew, and AVIF needs more than a browser to make.

How AI Reads Your Text: Tokens, Costs, and Context Windows Explained
Language models do not read words — they read tokens. Understanding tokens is the key to predicting what an AI request will cost and whether your prompt will even fit. Here is how it works, in plain English.